Phenopackets v2
PXF stands for Phenotype eXchange Format. Pheno-Ranker reads Phenopackets v2 serialized as JSON or YAML without requiring a custom configuration.
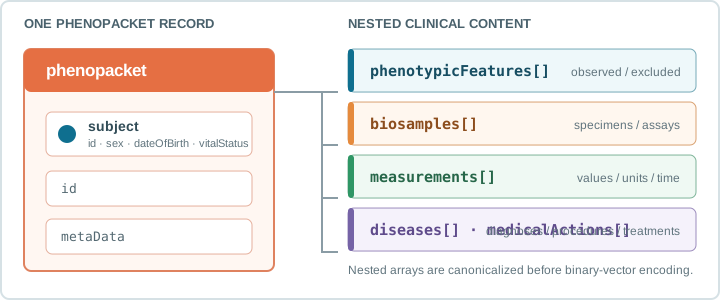
Phenopackets organize clinical information into top-level elements such as the subject, phenotypic features, diseases, measurements, medical actions, and interpretations. Pheno-Ranker compares the categorical content within those elements.
Browse an example Phenopacket
Run This Format
- Desktop
- CLI
- Select New analysis, then choose cohort or patient mode.
- Open User files and select the Phenopacket JSON/YAML as the reference.
- In patient mode, also select one target Phenopacket.
- Select Run analysis.
No configuration file is required. See the Desktop guide for the visual workflow.
For cohort mode:
pheno-ranker -r pxf.json
For patient mode:
pheno-ranker -r pxf.json -t target.json
The commands create matrix.txt and rank.txt, respectively. Continue with
Cohort Mode, Patient Mode, or the full CLI Reference.
Try the Sample Cohort
Download a simulated cohort of 100 Phenopackets:
curl -L https://raw.githubusercontent.com/CNAG-Biomedical-Informatics/pheno-ranker/main/share/ex/pxf_random_100.json -o pxf.json
No manual transposition is required. Pheno-Ranker automatically handles nested arrays, including PXF-specific genomic interpretations, before comparison.
To compare only selected top-level elements in cohort mode, use --include-terms:
pheno-ranker -r pxf.json --include-terms phenotypicFeatures diseases
Patient mode requires one target Phenopacket. To extract one from the sample:
pheno-ranker -r pxf.json --patients-of-interest Phenopacket_1
This creates Phenopacket_1.json. Rank the reference cohort against it:
pheno-ranker -r pxf.json -t Phenopacket_1.json
Automatic Nested-Array Handling
From v1.08 onward, array order does not prevent equivalent nested PXF content from matching. This applies to structures such as diagnostic markers, disease stages, typed quantities, and treatment dose intervals. See the algorithm description for the general canonicalization method.
PXF-specific handling of genomic interpretations
Genomic interpretations require one additional PXF-specific step. Their source
objects can contain patient-specific values in id and
subjectOrBiosampleId. If those values became part of a comparison key, the
same disease or gene would appear different in every patient.
Pheno-Ranker therefore organizes each interpretation by the diagnosed disease
identifier and each genomic interpretation by its gene identifier. For example,
an interpretation containing disease OMIM:148600, gene HGNC:25662, status
CAUSATIVE, and progress status SOLVED produces comparison keys such as:
interpretations.OMIM:148600.genomicInterpretations.HGNC:25662.interpretationStatus.CAUSATIVE
interpretations.OMIM:148600.genomicInterpretations.HGNC:25662.variantInterpretation.variationDescriptor.geneContext.symbol.AAGAB
interpretations.OMIM:148600.progressStatus.SOLVED
The patient-specific identifiers are not used in these keys, allowing the same
disease and gene content to match across Phenopackets. This transformation is
automatic when interpretations is included in the comparison.